It’s a reference to a glorious image, not sure if it’s real, but it’s been around for a while:
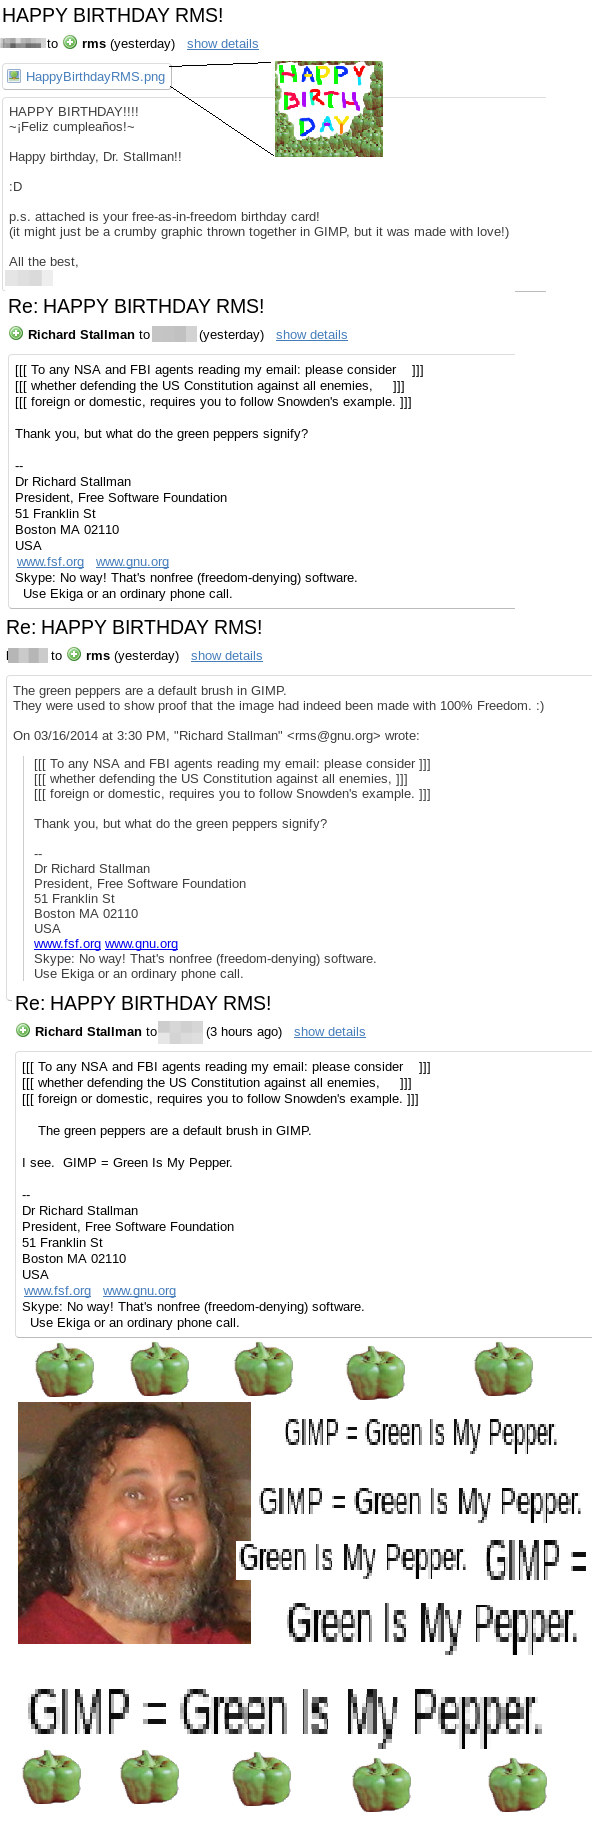
It’s a reference to a glorious image, not sure if it’s real, but it’s been around for a while:
My bios/similar are either empty or whatever I put there as a teen… Except for one where I put “Green Is My Pepper”, I should use that more.
Ahh, is it Not Quite Almost Christmas Time already?
If you want https it’s gotta be a external DNS record anyway
Not sure what you mean by that, but off the top of my head, you can get certificates via challenges that prove DNS control (rather than checking if the DNS points to your server), and you can get wildcard certificates so you don’t even have to expose the existence of subdomains.
And that’s ignoring the option of using your own CA, which only really works with your own devices, but for local access might be viable.
Probably because, to my knowledge, there isn’t a better/more ethical alternative than Linux, so the claim being made is extreme to an absurd degree. It proposes no alternative, and off the top of my head, I can only think of using outdated unmaintained versions of software, not using any computers at all, or switching to something very niche (is FreeBSD slopfree?).
Going to go with a video game: Outer Wilds. The game is very story and mystery oriented, so I don’t want to spoil it, as that can ruin the experience. In short though, it’s an exploration game where you get to do your first flight around a miniature solar system - exploring it freely without a linear sequence or quest markers.
The story is told in a nonlinear way, depending on how you explore it, and the way it comes together and the conclusion it reaches were amazing to discover.
Are supposed to, and generally are, but there is a risk of somebody making unsourced changes and you seeing the article before it’s caught. Not a big deal for popular articles, but there are a lot of niche topics.
Nope, the rise in water shows exclusively the volume. Density is derived using volume and mass, with mass being measurable by weighing. The only factor density plays directly is indeed floating, but you can just push the sphere under with a thin rod without significantly impacting the measurement.
It’s generally simple - water has some volume, sphere has some volume. Assuming a cylindrical container, the base of the cylinder is known, and the volume of it is equal to the volume of water, which means you can derive the height (or vice versa). If you now add the sphere, the sphere pushes out the water, which means you add the volume of the sphere to the water - and if you measure the height, you can calculate the total volume of water+sphere, and subtract the initial volume of water to isolate the volume of the sphere.
It’s not as simple as one singular aspect, and I don’t know if I might’ve been fine with it if it was actually open and free from the start. But where I draw the line on ethics is with the usage of data without permission to create models intended to reproduce the data - which means laundering the data, reproducing the patterns from it to create competition/replacements for the people who made the creative work it’s trained on.
The monetization is a more complicated aspect, because it is also fact that at this point the big GenAI companies are dominating the market and consuming an unreasonable amount of resources to grow, and with that any use of LLMs is supporting that market. Using the services of those companies obviously supports them, publicly using LLMs supports the legitimacy of the market, and if the current trend continues, private use of selfhosted LLMs is making yourself dependent on them, and it sure seems like the tech market is doing its best to make the necessary hardware unavailable to people, meaning you’re setting yourself up to be dependent on the companies in the future.
But, that’s the fun thing - this is a short explanation of my opinion, because this is a complex topic, and I’m not writing this out every time, and people wouldn’t read it. My specific opinion is that governments need to catch up on copyright law, and hopefully GenAI is a bubble that bursts soon. If anti-GenAI sentiments become more widespread, maybe it’ll happen. If not, then I’ll have to eventually give up on my morals, but for now I can only hope it doesn’t come to that.
Again, this is an expression of your ignorance, not reality.
OLMo 2 was trained on Wikipedia and other fully public forums. Its training sources and data is fully accessible and open.
Decided to check out the first example quickly. It’s hard to dig through the information, but following the chain of sources:
In the first stage, which covers over 90% of the total pretraining budget, we use the OLMo-Mix-1124, a collection of approximately 3.9 trillion tokens sourced from DCLM, Dolma, Starcoder, and Proof Pile II.
As part of DCLM, we provide a standardized corpus of 240T tokens extracted from Common Crawl
So, it’s using data from Common Crawl. What data, exactly? That’d be harder to dig up. DCLM has a repository, but they don’t make an effort to point out how, or if, they’re filtering the data.
What I can quickly find is information from Common Crawl itself, which is the ultimate source of data. On that I can immediately see only two things:
github.com. I doubt github has that many pages of non-user-generated content, so the question is… What data is going in there, who wrote it, and did anybody agree to that? What about other websites from those top domains, such as blogspot.com, wordpress.org, readthedocs.io? I doubt they got permission to use the 17175161 pages of content from blogspot they’ve scraped.So yeah, maybe there’s a “good” model out there I’d actually accept, but I’ve seen “open” models being released, and I can’t possibly check all of them, just checking the websites for one of the sources for one of the models took 20 minutes here, if I wanted to verify this properly I’d have to setup the tooling to query the terabytes of data for this source, and all others, and even there I’m not sure if I’d find answers.
If you’re upset with Sam Altman and ChatGPT, then you can simply say “Sam Altman is a thief, and ChatGPT uses stolen data.” Which is infinitely more defendable than “AI is trained on stolen data and is unethical.”
The issue is, I’d say the same applies to every model that produces useful outputs. LLaMa, Anthropic, Grok, DeepSeek, whatever else is out there. If you tell somebody that the LLM they’re using is unethical, they’ll nust go use another convenient corporate model.
And “public data” is not enough for me, because that typically means scraping copyrighted content from public websites, I’m not aware of a model that uses only data with permission (either explicit or granted by the license) that’s useful, and the people who need to hear about ethical problems with GenAI especially don’t know about that.
It can’t be FOSS but not Libre, the Free in FOSS means Libre. And it also can’t be FOSS but not opensource, of course.
If I’m having a direct discussion with somebody, then I’ll make it clear what I’m talking about, and if they engage in a conversation about ethics, I’ll explain why those things are unethical.
But if I wanted to post a public message to voice my sentiment, I don’t think trying to post a long explanation every time would do any good, most people would probably just skip it when they saw it’s longer than a couple lines of text. So for those cases, I’d say you have to go down to the level of current discourse to engage with the masses on their terms if you want to be heard.
The problem is that the general public has adopted “AI” to mean the current popular machine learning thing, the general category of “generative AI”, and if you want a message about it to be received broadly, you need to use terms people will understand.
In my case, I’m not aware of any GenAI models that produce useful output that I’d consider to be ethical, so I support this message.
Technically vanilla RimWorld already has “Lovin’”, which colonists sharing a bed can do, and the DLC has colonist pregnancy, IUDs, babies, and I think even artificial insemination (though it’s been a long time since I played without mods, so I could be mixing something up)
But really, given sufficient time, any sufficiently moddable game will have a horny mod made.
the likelihood of reinstalling is high.
At least with Arch, I don’t imagine needing to reinstall, worst case I should be able to reinstall all packages from a live image.
But the removed count only includes a one year period and caps out at 250, how would you find the new average?
It’s surprisingly simple, if you have two cameras side by side, you’re capturing two images where the camera is moved horizontally relative to the subject. If you now instead take two pictures where you move the subject horizontally relative to the camera, you’re achieving the same effect on the subject in the images. This means you won’t get a correct effect on every video, and the background will be unaffected, but it can work.
Regarding osu’s source code, I think the original osu (osu!stable) is closed-source, and I think the servers might be closed-source, but I believe osu!lazer, the new reimplementation in C#, is fully opensource. It’s an ongoing effort and a long-term migration it’s in the middle of, but lazer looks great and I think it’s already meant to be the main version now.
This is AI slop