This is not a SFW instance. NSFW communities will be tagged, and efforts will be made to keep SFW communities clean, but proceed at your own comfort level.
The crazy thing is they aren’t really designed for that, especially the reasoning part.
I pictured LLMs proliferating in the way SGLang was taking it: fill in the blank. You’d give raw completion models (not chat finetunes) chunks of structured content (like JSON schemas, names in fields, more complex schemes filled programatically) and it would fill in fields, with intelligent context caching. Like, if you needed to finish a programming function, maybe you give it the file as context and guide it along.
Temperature based sampling felt like a quick hack, just until either looping or structured sampling was figured out.
…But they didn’t fix any of that.
Papers came out on the issues. But the big AI houses didn’t implement any of it. They basically kept it exactly the same and just kept scaling it to burn more compute.
What I am getting at is that OpenAI/Anthropic development is way, way more conservative than anyone thinks, and they basically took temporary hacks and made them bigger. That’s why you can’t trust the code they churn out, because random mistakes and so many other issues are literally part of their core.
Then they turn around and sell them as confident engagement engines…
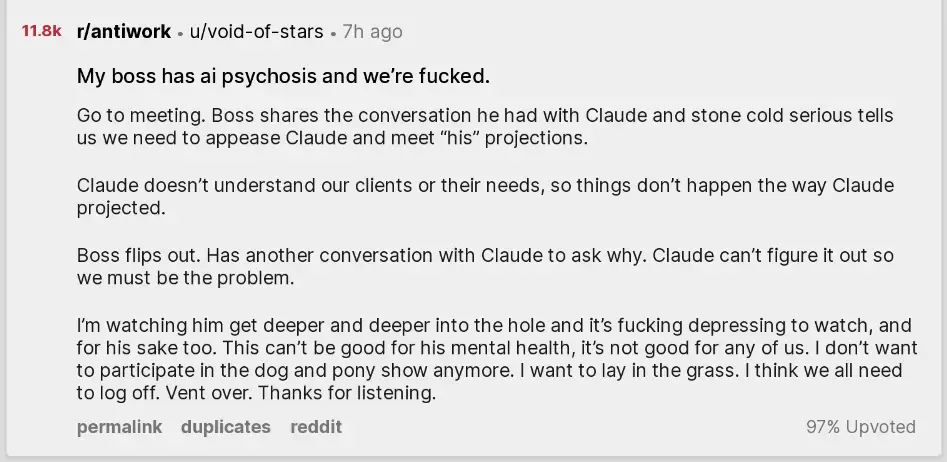
The crazy thing is they aren’t really designed for that, especially the reasoning part.
I pictured LLMs proliferating in the way SGLang was taking it: fill in the blank. You’d give raw completion models (not chat finetunes) chunks of structured content (like JSON schemas, names in fields, more complex schemes filled programatically) and it would fill in fields, with intelligent context caching. Like, if you needed to finish a programming function, maybe you give it the file as context and guide it along.
Temperature based sampling felt like a quick hack, just until either looping or structured sampling was figured out.
…But they didn’t fix any of that.
Papers came out on the issues. But the big AI houses didn’t implement any of it. They basically kept it exactly the same and just kept scaling it to burn more compute.
What I am getting at is that OpenAI/Anthropic development is way, way more conservative than anyone thinks, and they basically took temporary hacks and made them bigger. That’s why you can’t trust the code they churn out, because random mistakes and so many other issues are literally part of their core.
Then they turn around and sell them as confident engagement engines…
It’s utterly mind boggling to me.